Views, pipelines & triggers
This page is a task walkthrough: you'll learn how to materialize a view, how to run pipelines manually, how to schedule triggers and how to tie individual steps together into a master pipeline.
Looking for the complete field-by-field explanation per screen? You'll find it in the frontend reference: Data Engineering → Materialized views and Load Management (Run pipelines, Triggers, Master pipelines). This page summarizes how you do it; those pages describe every field of the screen.
Materializing a view
A materialized (persisted) view stores the result of a database view in a real table. Reports then read directly from a table and don't have to recompute a (possibly slow) view every time.
From v1.57, a materialized view is a regular source in Yres. You register the view the same way you register a table from a source system, and it loads through the same engine: from STAGE into the history layer, with the same load types, the same history, deltas and archiving, and with its own line in monitoring. The only difference is that you choose the target location yourself: a schema and table name of your own.
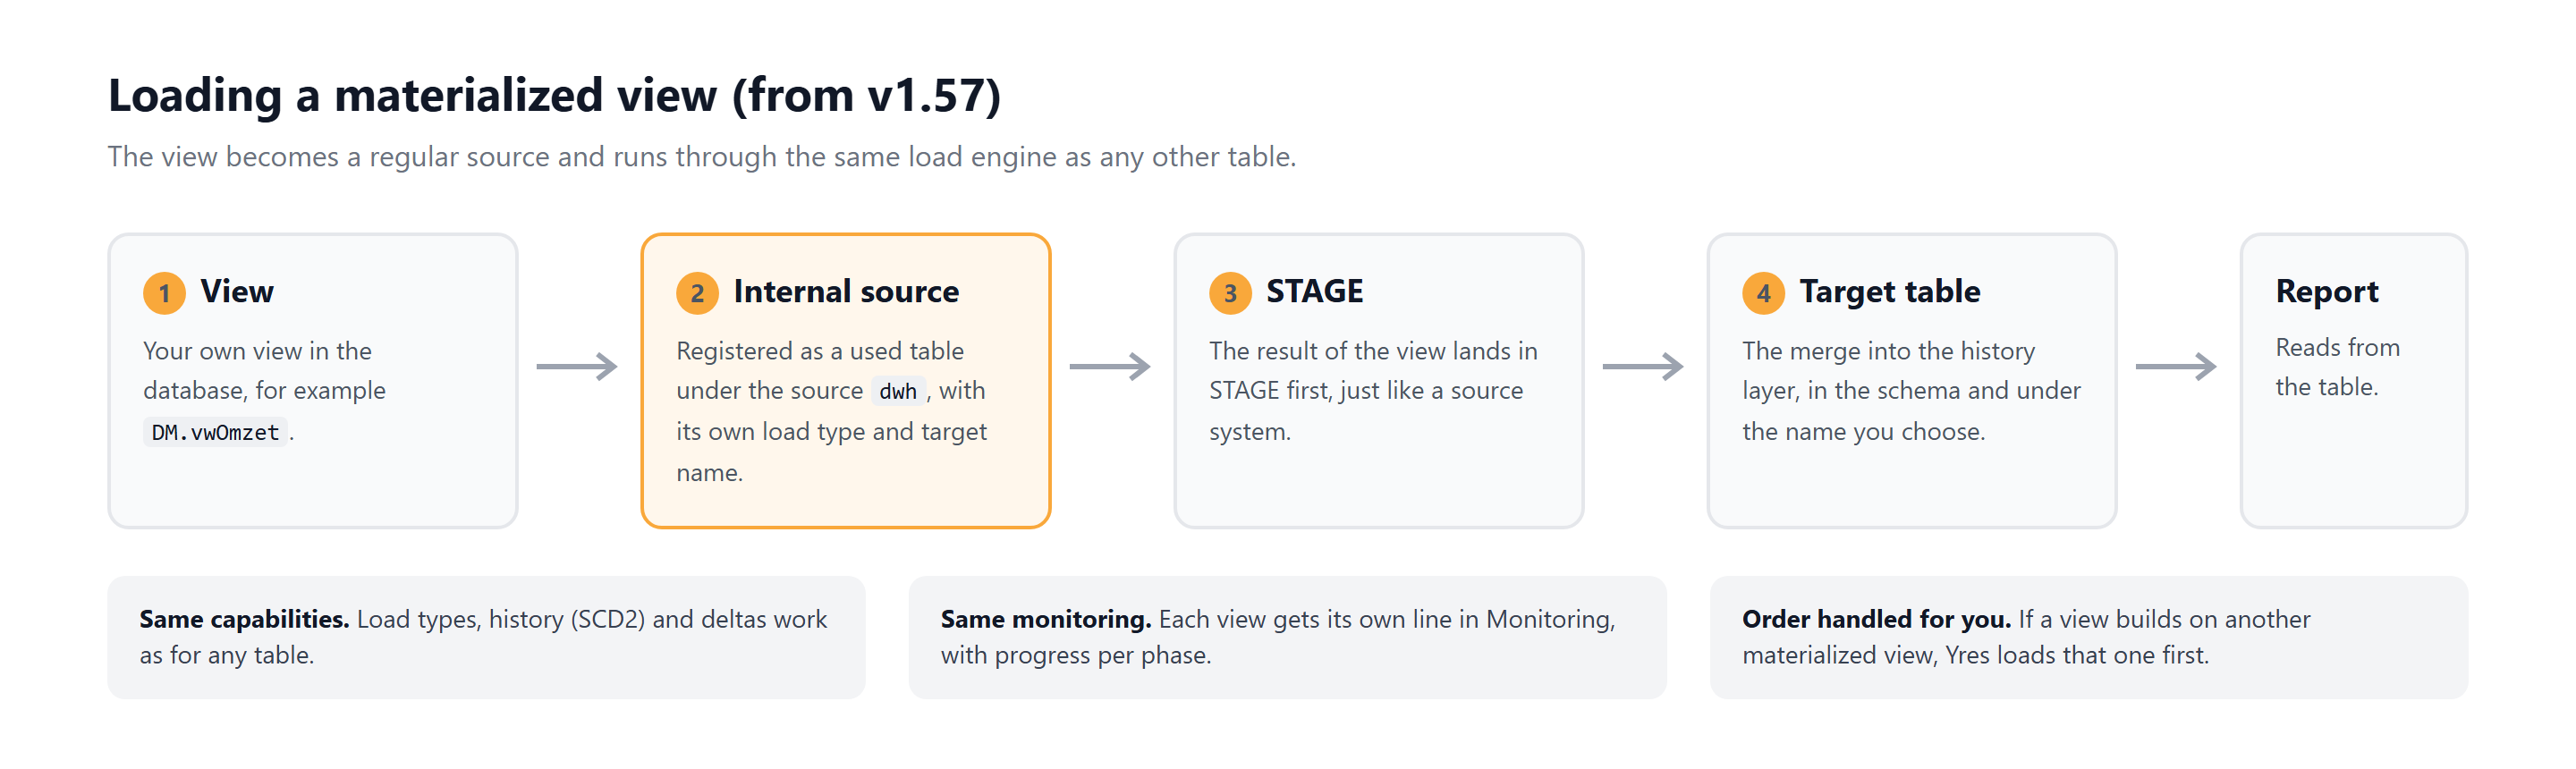
How a materialized view loads from v1.57: through the same steps as any other table.
Prerequisite: the view already exists in the database. Yres materializes that view; it does not create it for you. Create the view, for example, with SQL Server Management Studio (SSMS), such as a view DM.Vw760 in the IRIS_DWH database. It has to be one of your own views: Yres's own views cannot be registered as a source.
You manage materialized views in the webapp under Data engineering → Materialized views (/dataengineering/materializeviews). For each view the screen shows the source (SourceSchema, SourceTable), the target (TargetSchema, TargetTable) and the load settings.
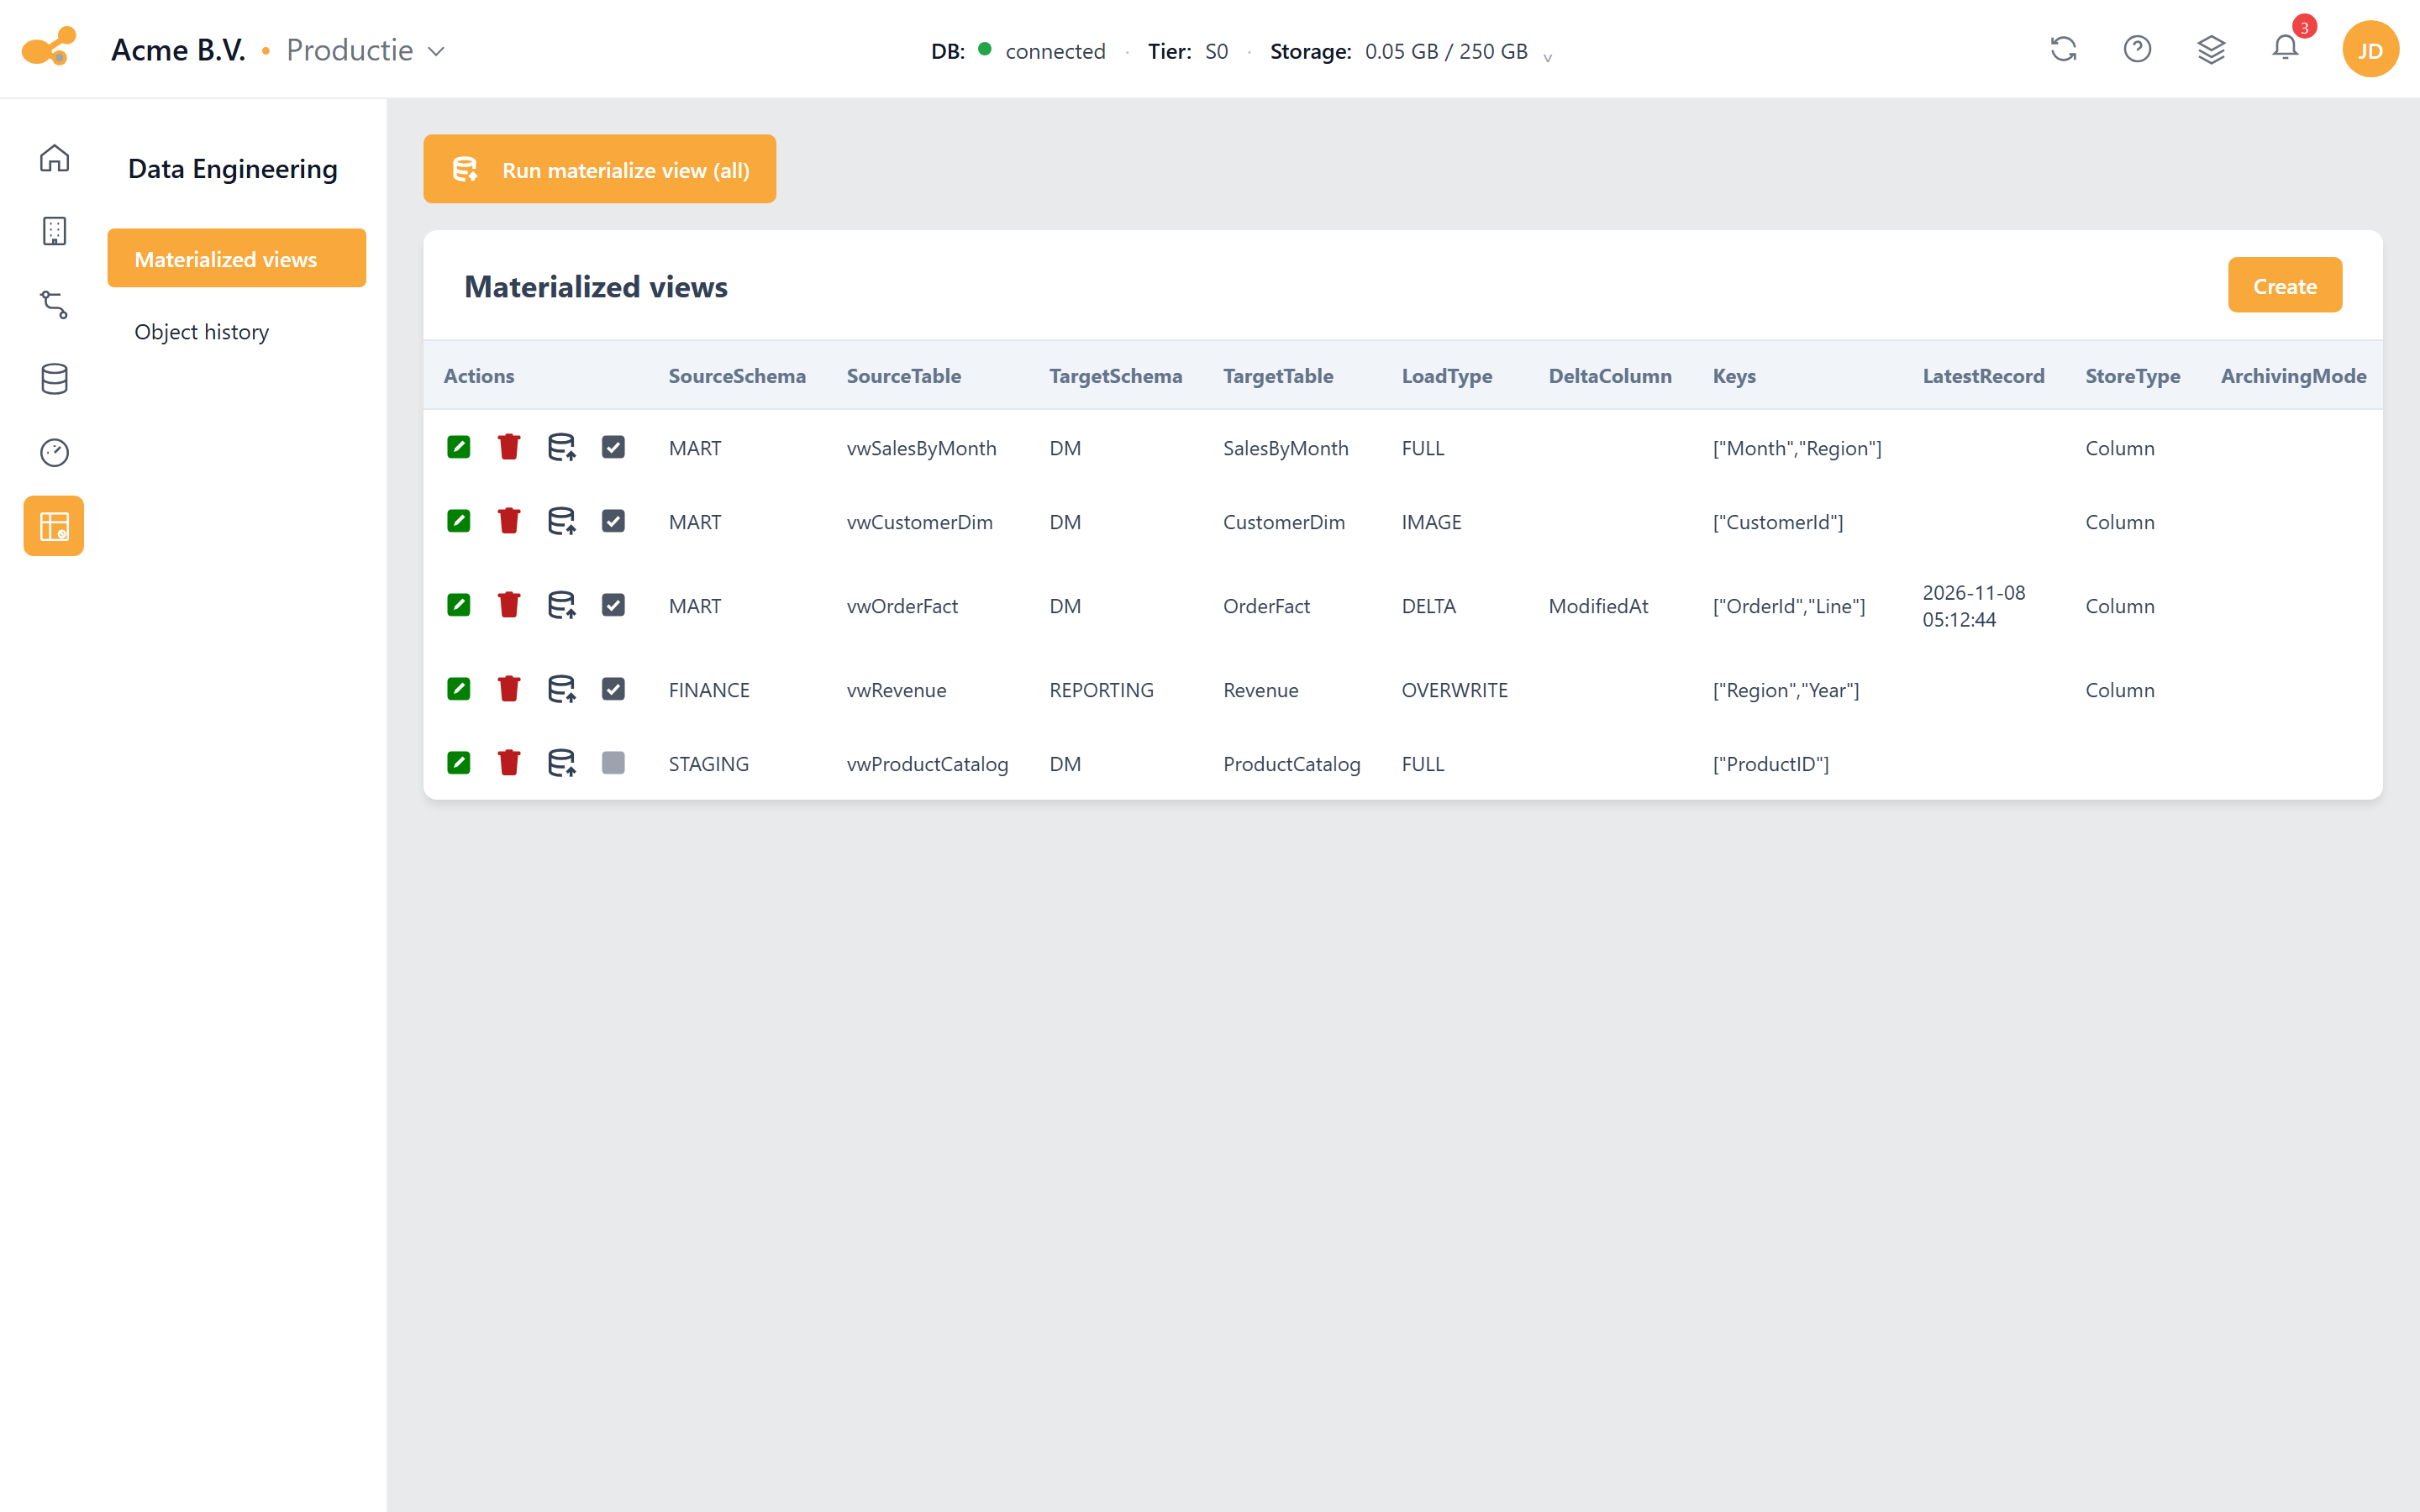
The Materialized views screen (from v1.57): per view the source, the target and the load settings. The last row is deactivated and therefore shows an empty box.
Steps (from v1.57)
- Open Data engineering → Materialized views and click Create.
- If you have several environments, first choose the project and the change the registration belongs to, just as for any other table.
- Choose the schema and the view (in the table field). The data platform is fixed to Data Warehouse.
- Select the columns you want to load.
- Choose the load type. You can choose from
FULL,DELTA,DELTAIMAGE,IMAGE,OVERWRITEandRELOAD. ForDELTAandDELTAIMAGEyou specify the view's delta column. See Load types for what each type does with the history. - Choose the key. A view has no key of its own. Without an explicit choice, Yres uses all
NOT NULLcolumns together as the key. ForIMAGE,DELTAIMAGEandDELTAthe screen therefore shows a warning: preferably choose the key yourself, so the history builds up cleanly per record. - Go through the steps for additional options and archiving, as for a regular table.
- In the last step, fill in Target schema and Target table: where the materialized table lands. Both are required. The table name must be unique across all registrations, so across other schemas as well. Below them you see the resulting STAGE Target and HIS Target for reference.
- Save. Yres registers the view and creates the target table.
- Materialize straight away with the row action Run materialize view, or run all views at once with Run materialize view (all).
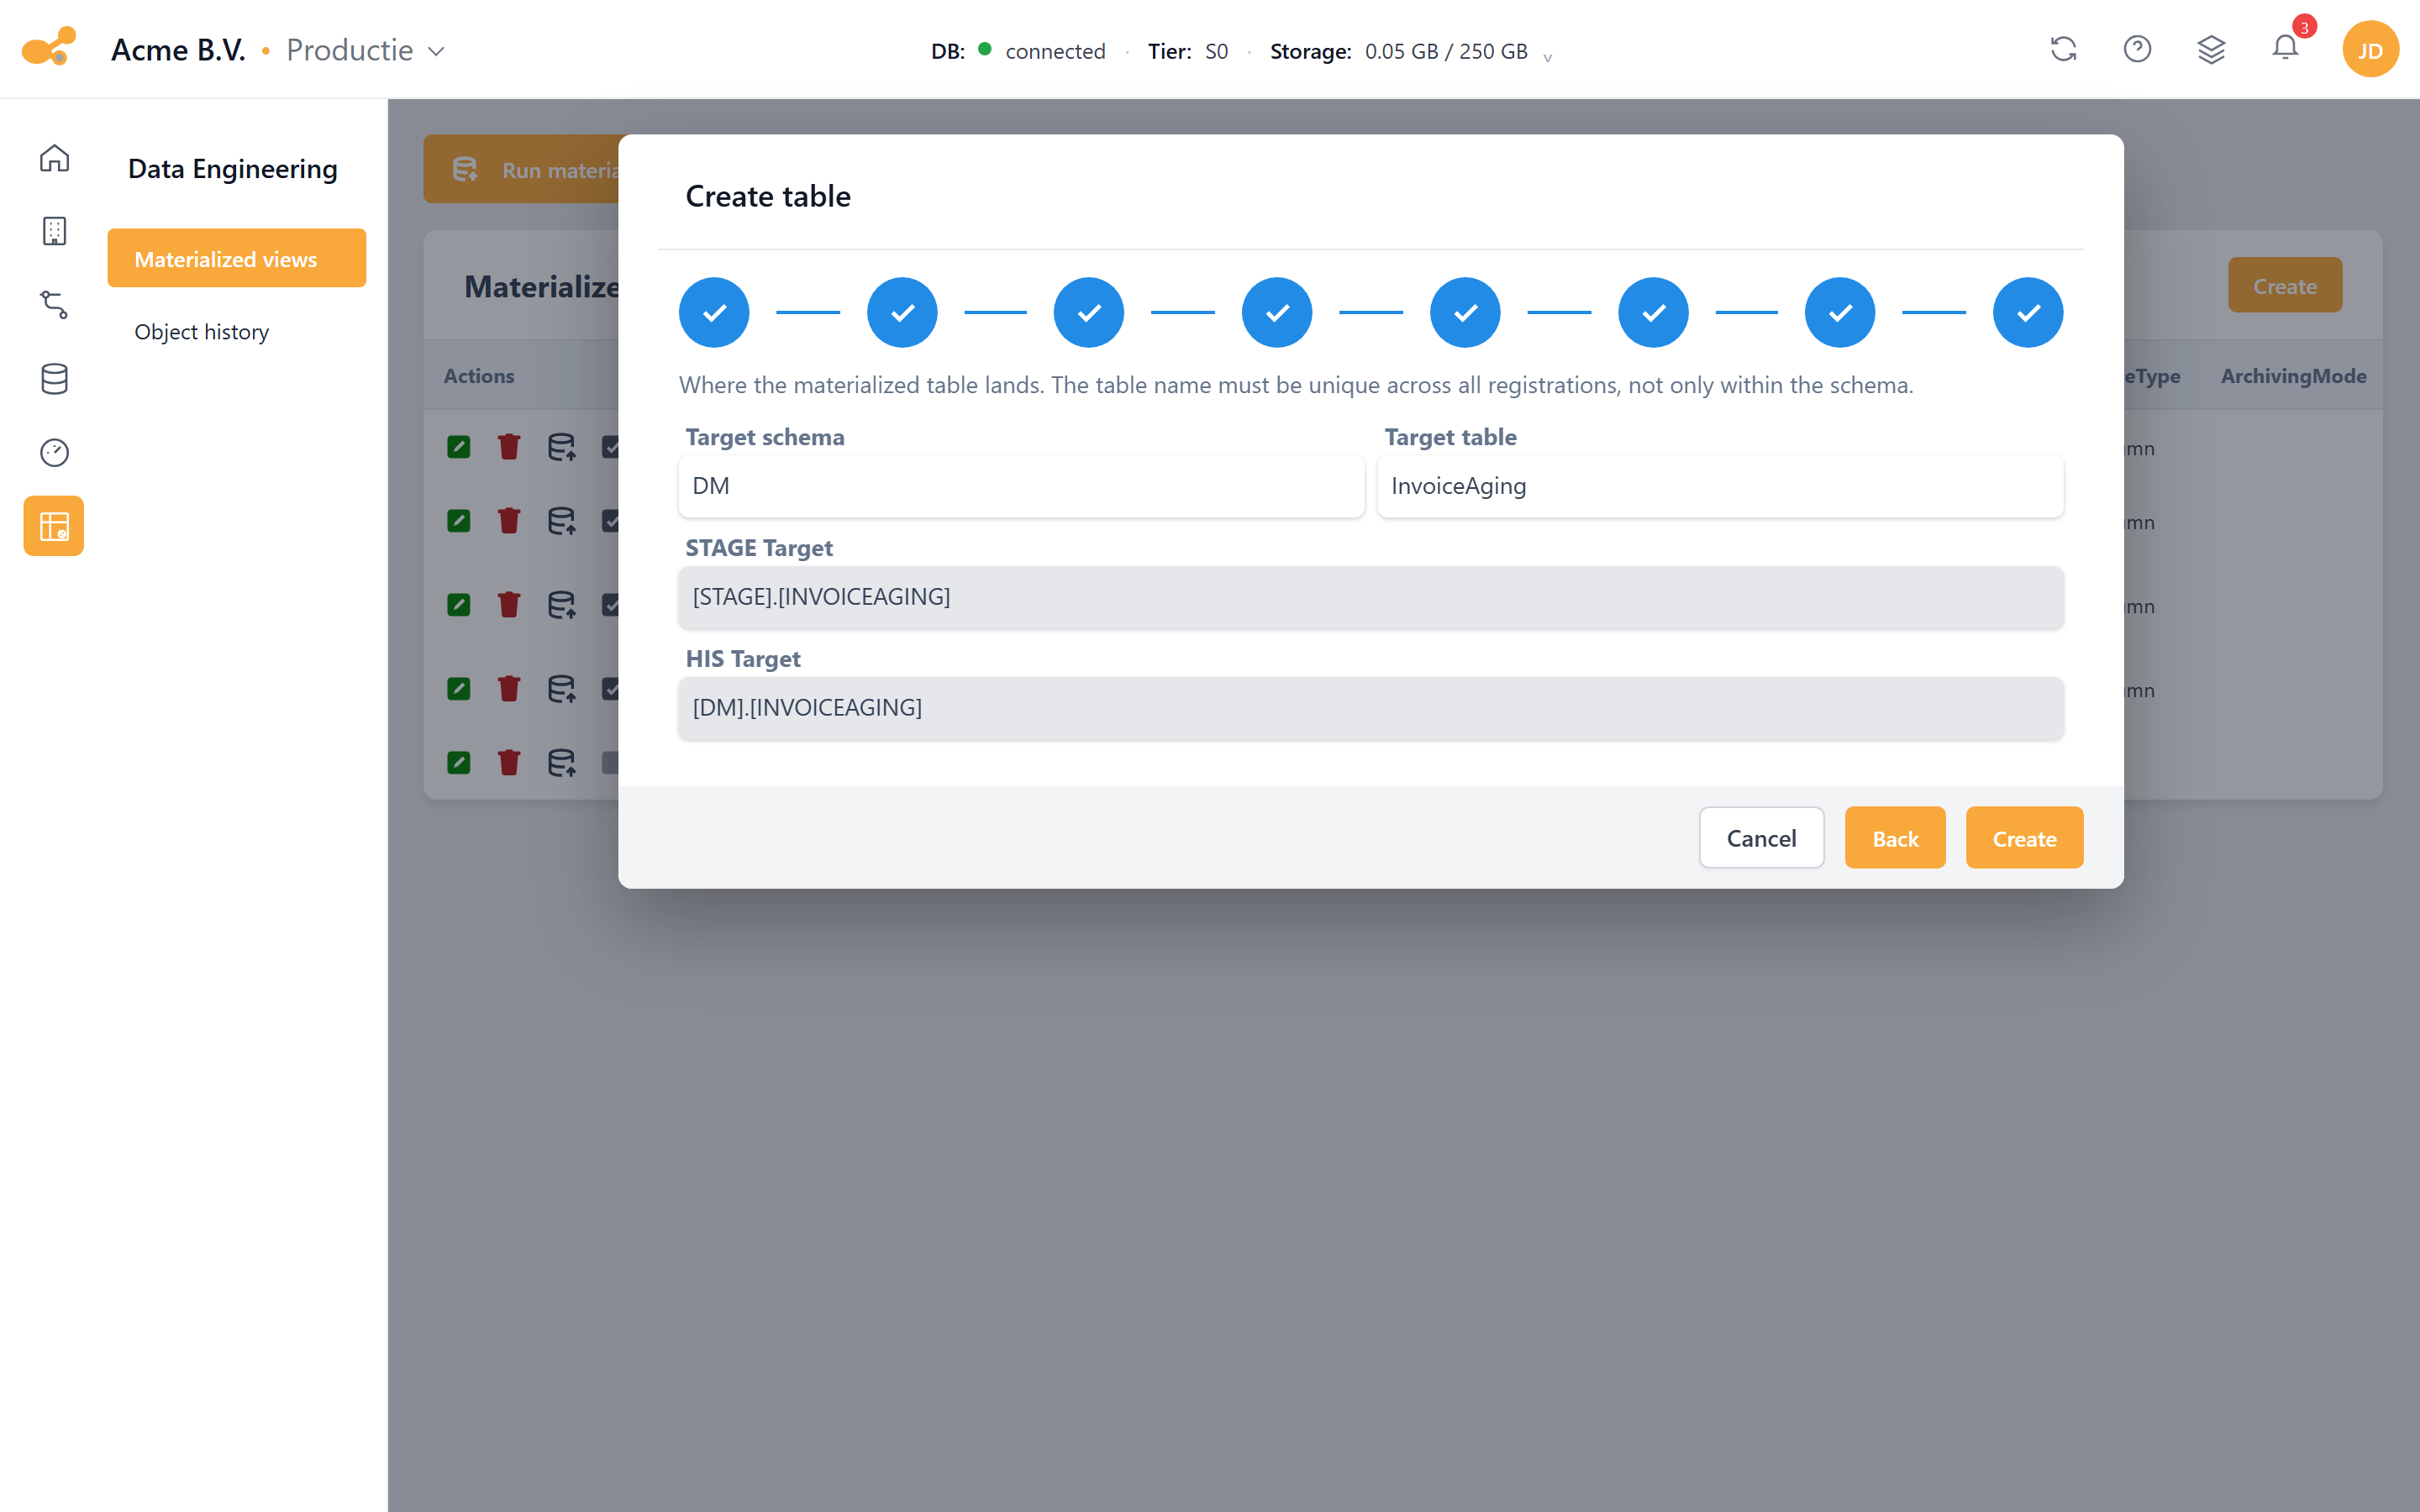
The target step of the wizard: you choose the schema and table name yourself. You pick the view itself earlier, in the schema and table step.
To stop materializing a view for a while, use the row action to deactivate the table. The same action switches it back on later. When you edit a view, leave Target schema and Target table empty to keep the current target; if you fill in both, the table moves to that new location.
If view B reads from the materialized table of view A, Yres loads A first automatically. The order follows from the dependencies between the views; setting a Level is no longer needed. Yres reads those dependencies from the definitions of your views and functions. A reference that exists only in dynamic SQL falls outside that.
A materialized view is a registered table under the internal source dwh (source type INTERNAL). The views come from the source catalog [LoadManagement].[vwCatalog], which contains your own views alongside the regular Dictionary. The materialization is done by [LoadManagement].[spMaterializeViews]: for each view the procedure fills STAGE with the view's result and then lets [LoadManagement].[spLoadDWH] perform the merge into the history layer, exactly as for a source that comes in through ADF. The Materialize View pipeline calls this procedure. The same step (Materialize Views) also runs at the end of the Direct Workflow YRES and the Dynamic Workflow YRES: in a run over all sources (Source = ALL) it includes all views, in a trigger run (AUTO) the views linked to that trigger.
When upgrading to v1.57
Existing view persistence moves to the new mechanism automatically during the upgrade. Each active view is registered as an internal source with the same target schema and target table. Views that were set to Delta get load type DELTA with the same delta column; the others get OVERWRITE, so the table looks exactly as it did before. If you want to build up history, you then deliberately choose, for example, IMAGE per view.
During the conversion the target table is created again. The first materialization run after the upgrade fills it again. So start a Materialize View run straight after the upgrade, or let the next scheduled workflow do it.
A view that is itself a Yres object cannot be registered as an internal source. Such a view stays as it was. Health check 2.26 (Niet-gemigreerde persist-view, not-migrated persist view) points it out, so you can decide what to do with it.
Up to and including v1.56
On v1.56 and older you manage materialized views in the Data engineering → View persistence screen (/dataengineering/viewpersistence), which reads from Loadmanagement.vwViewPersistence.
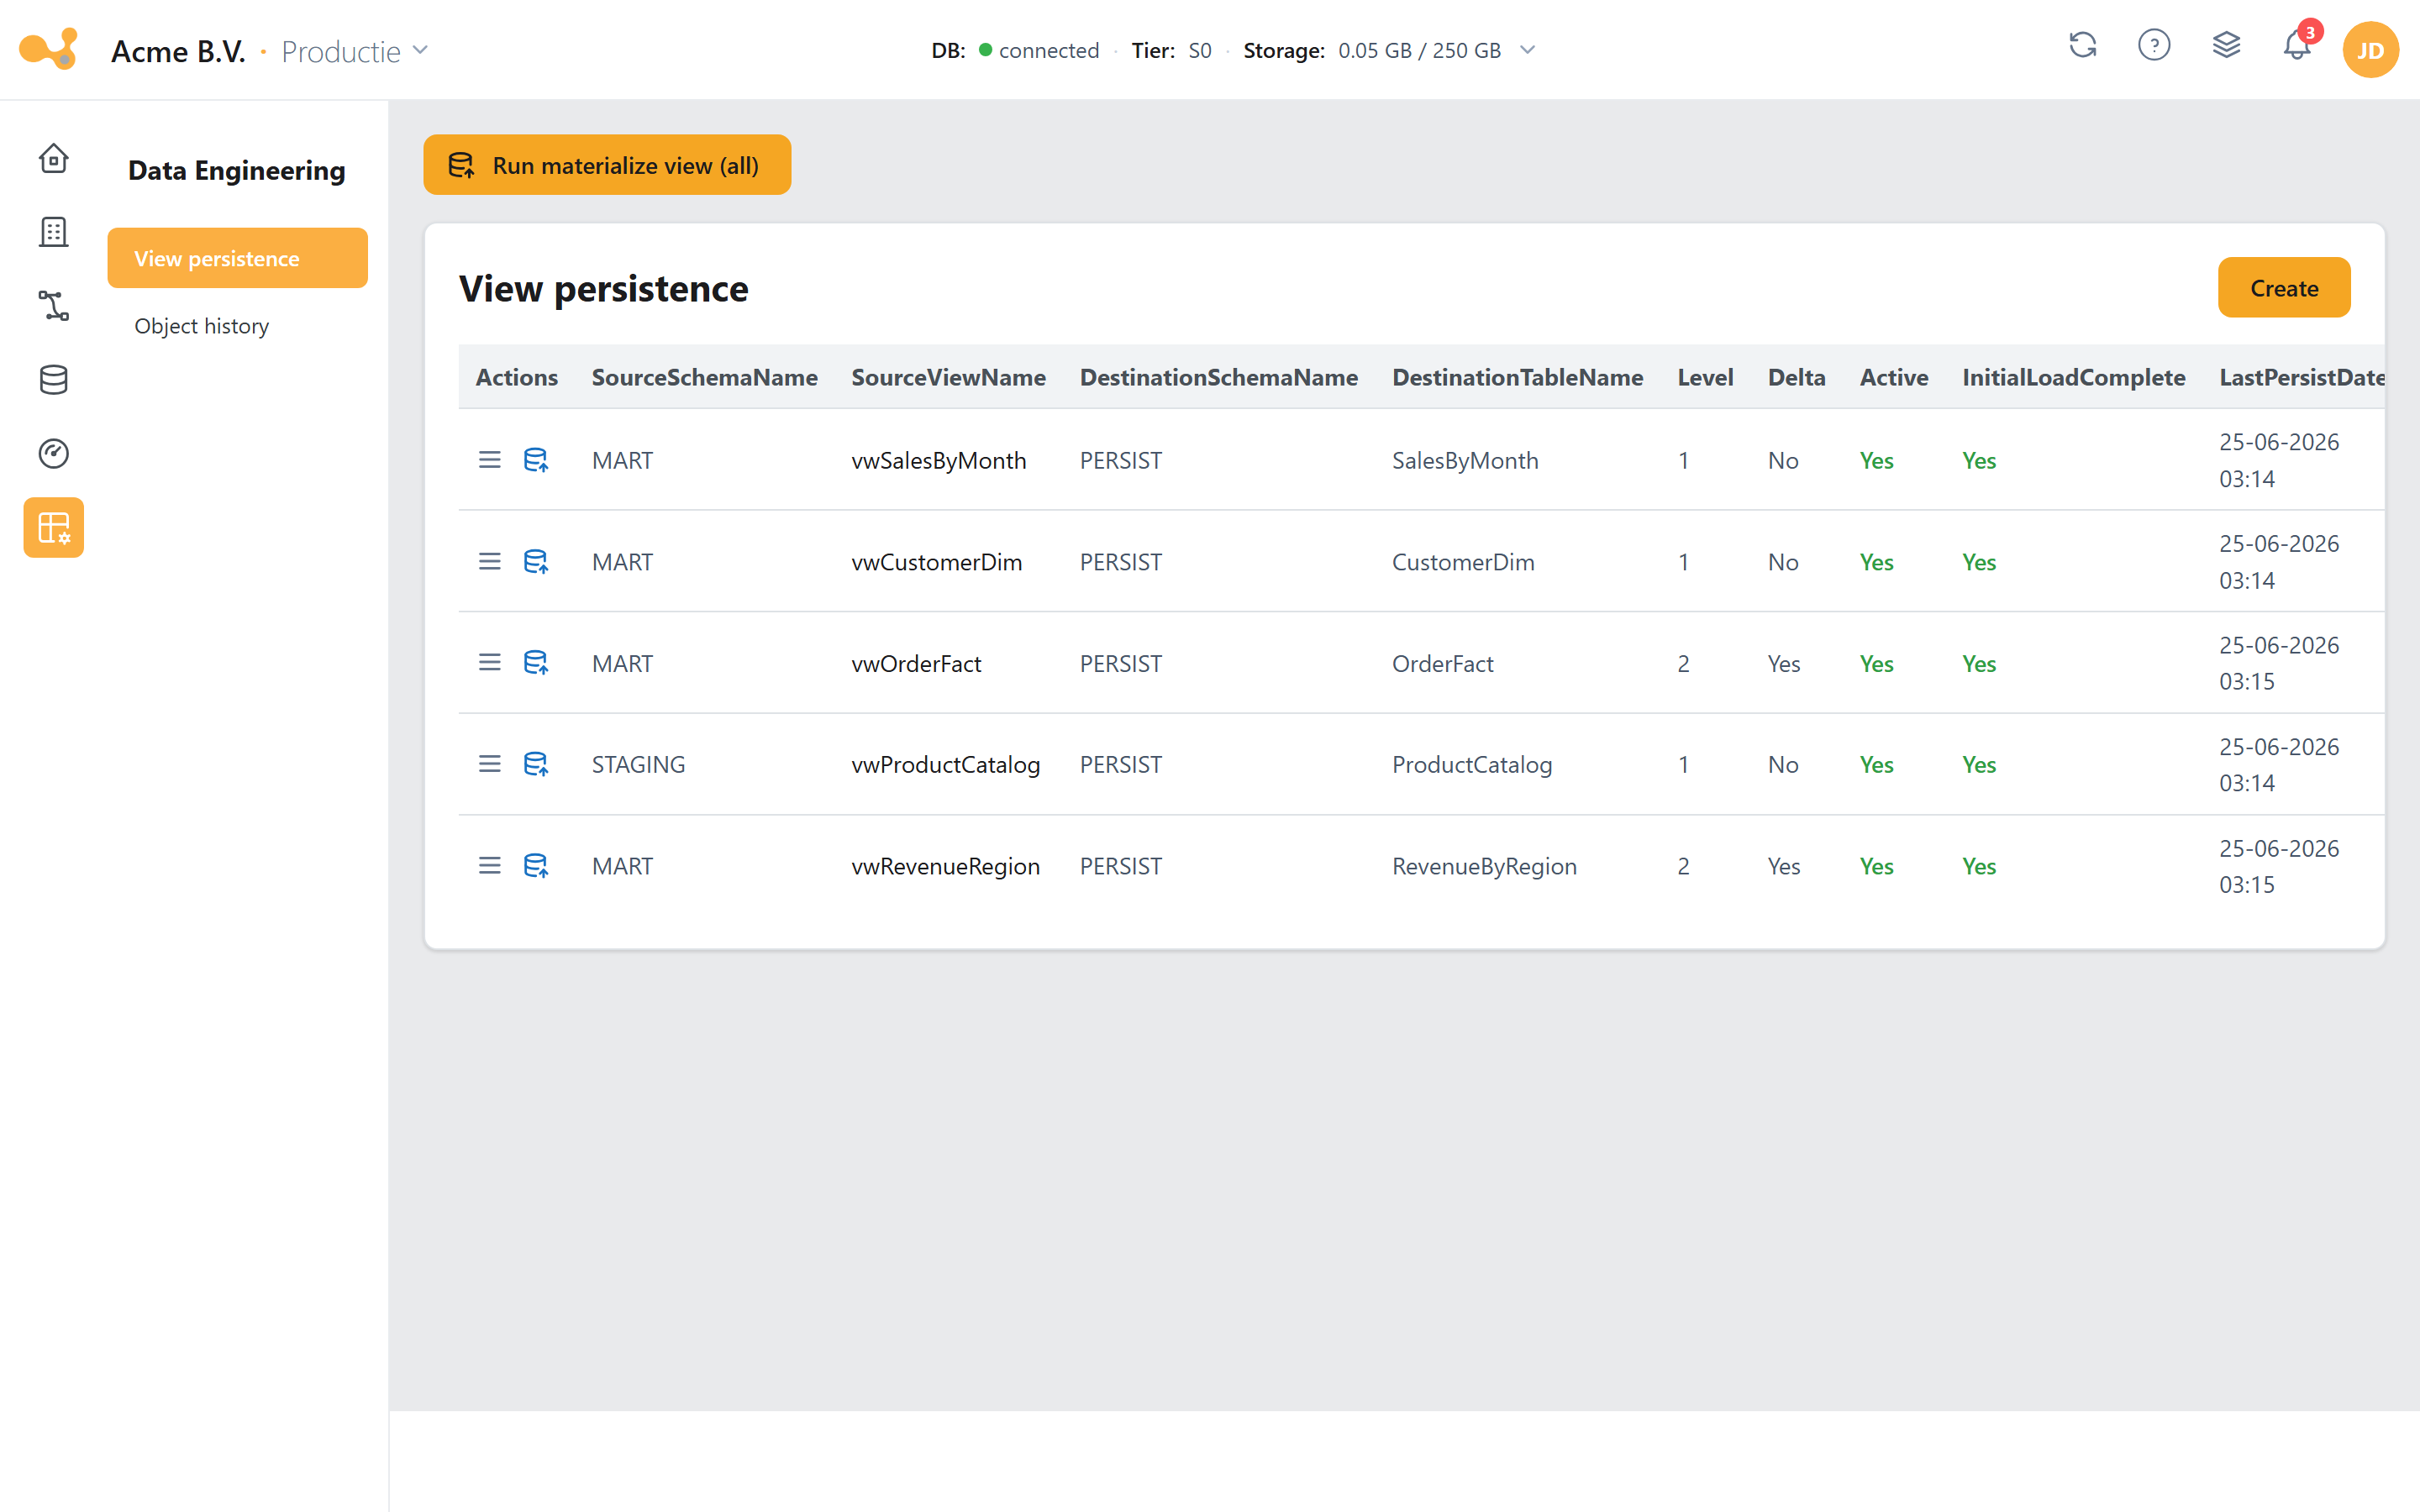
The View persistence screen (up to and including v1.56): the persistence table with the creation form (Create persisted view) below it.
You click + Add persisted view, choose the source (SourceSchemaName + SourceViewName) and the destination (DestinationSchemaName + DestinationTableName), set a Level for the order (a lower Level is materialized first) and choose Full (the whole view again on every run) or Delta (only changed records, with a source object and a DeltaColumn). You materialize with Run materialize view per row or Run materialize view (all). Under the hood, MaintainPersistView stores the configuration and spMaterializeViewToTable writes the view directly to the destination table.
Running pipelines manually
You start pipelines in Load Management → Run pipelines (/loadmanagement/runPipelines). The pipeline list is on the left, the runs of the selected pipeline on the right with filters by period and status.
Steps:
- Open Load Management → Run pipelines and select a pipeline on the left.
- Click Start pipeline. If the pipeline has parameters, the button reads Set parameters to start and a form opens.
- Fill in the parameters and confirm. The run appears in the runs table.
Two common cases:
- Refresh All Metadata — select the metadata pipeline on the left and click Start pipeline. This refreshes the source metadata (schemas, tables, columns) before you add tables.
- Dynamic Workflow YRES — this is the dynamic load workflow. Fill in: Source, Source schema and Source table, and optionally choose a Running tier (the tier the load runs on) and a Revert-to tier (the tier Yres scales back to afterwards). On older Yres versions this pipeline is still called
Dynamic Workflow IRIS; the app recognizes both names.
The actual loading happens in Azure Data Factory: the pipeline copies the source into STAGE and then calls [LoadManagement].[spLoadDWH]; progress is logged via [Monitoring].[spWriteLoadStatus]. You can stop a running run via the stop icon. See Data flow for the full flow.
Scheduling triggers
With a trigger you let a pipeline run automatically on a fixed interval. You manage triggers in Load Management → Triggers (/loadmanagement/triggers).
Steps:
- Open Triggers and select the pipeline you want a trigger for on the left.
- Click Create.
- Fill in:
- Name (required).
- Every / interval (a number) and Frequency:
Minute(s),Hour(s),Day(s),Week(s)orMonth(s). - For Week(s): a Day of the week. For Month(s): a Day of the month (1–31). For Day/Week/Month: a Time.
- If the pipeline has parameters (such as the Dynamic Workflow with Source/Schema/Table), fill those in in the second step.
- Click Submit. The trigger is created in ADF and started immediately; you can start, stop or delete it later from the triggers table.
The interface shows the hint "Timezone UTC(+1) will be used", but the trigger actually uses the time zone of the logged-in user (from your user settings), not a fixed UTC+1. Keep this in mind when scheduling.
Setting up a master pipeline
With master pipelines you tie existing Yres building blocks together into a single flow with conditional logic — for example deltas during the week and a full reload at the weekend, or a Power BI refresh that only runs after a successful load. You work in a visual editor (based on reactflow) under Load Management → Design master pipeline.
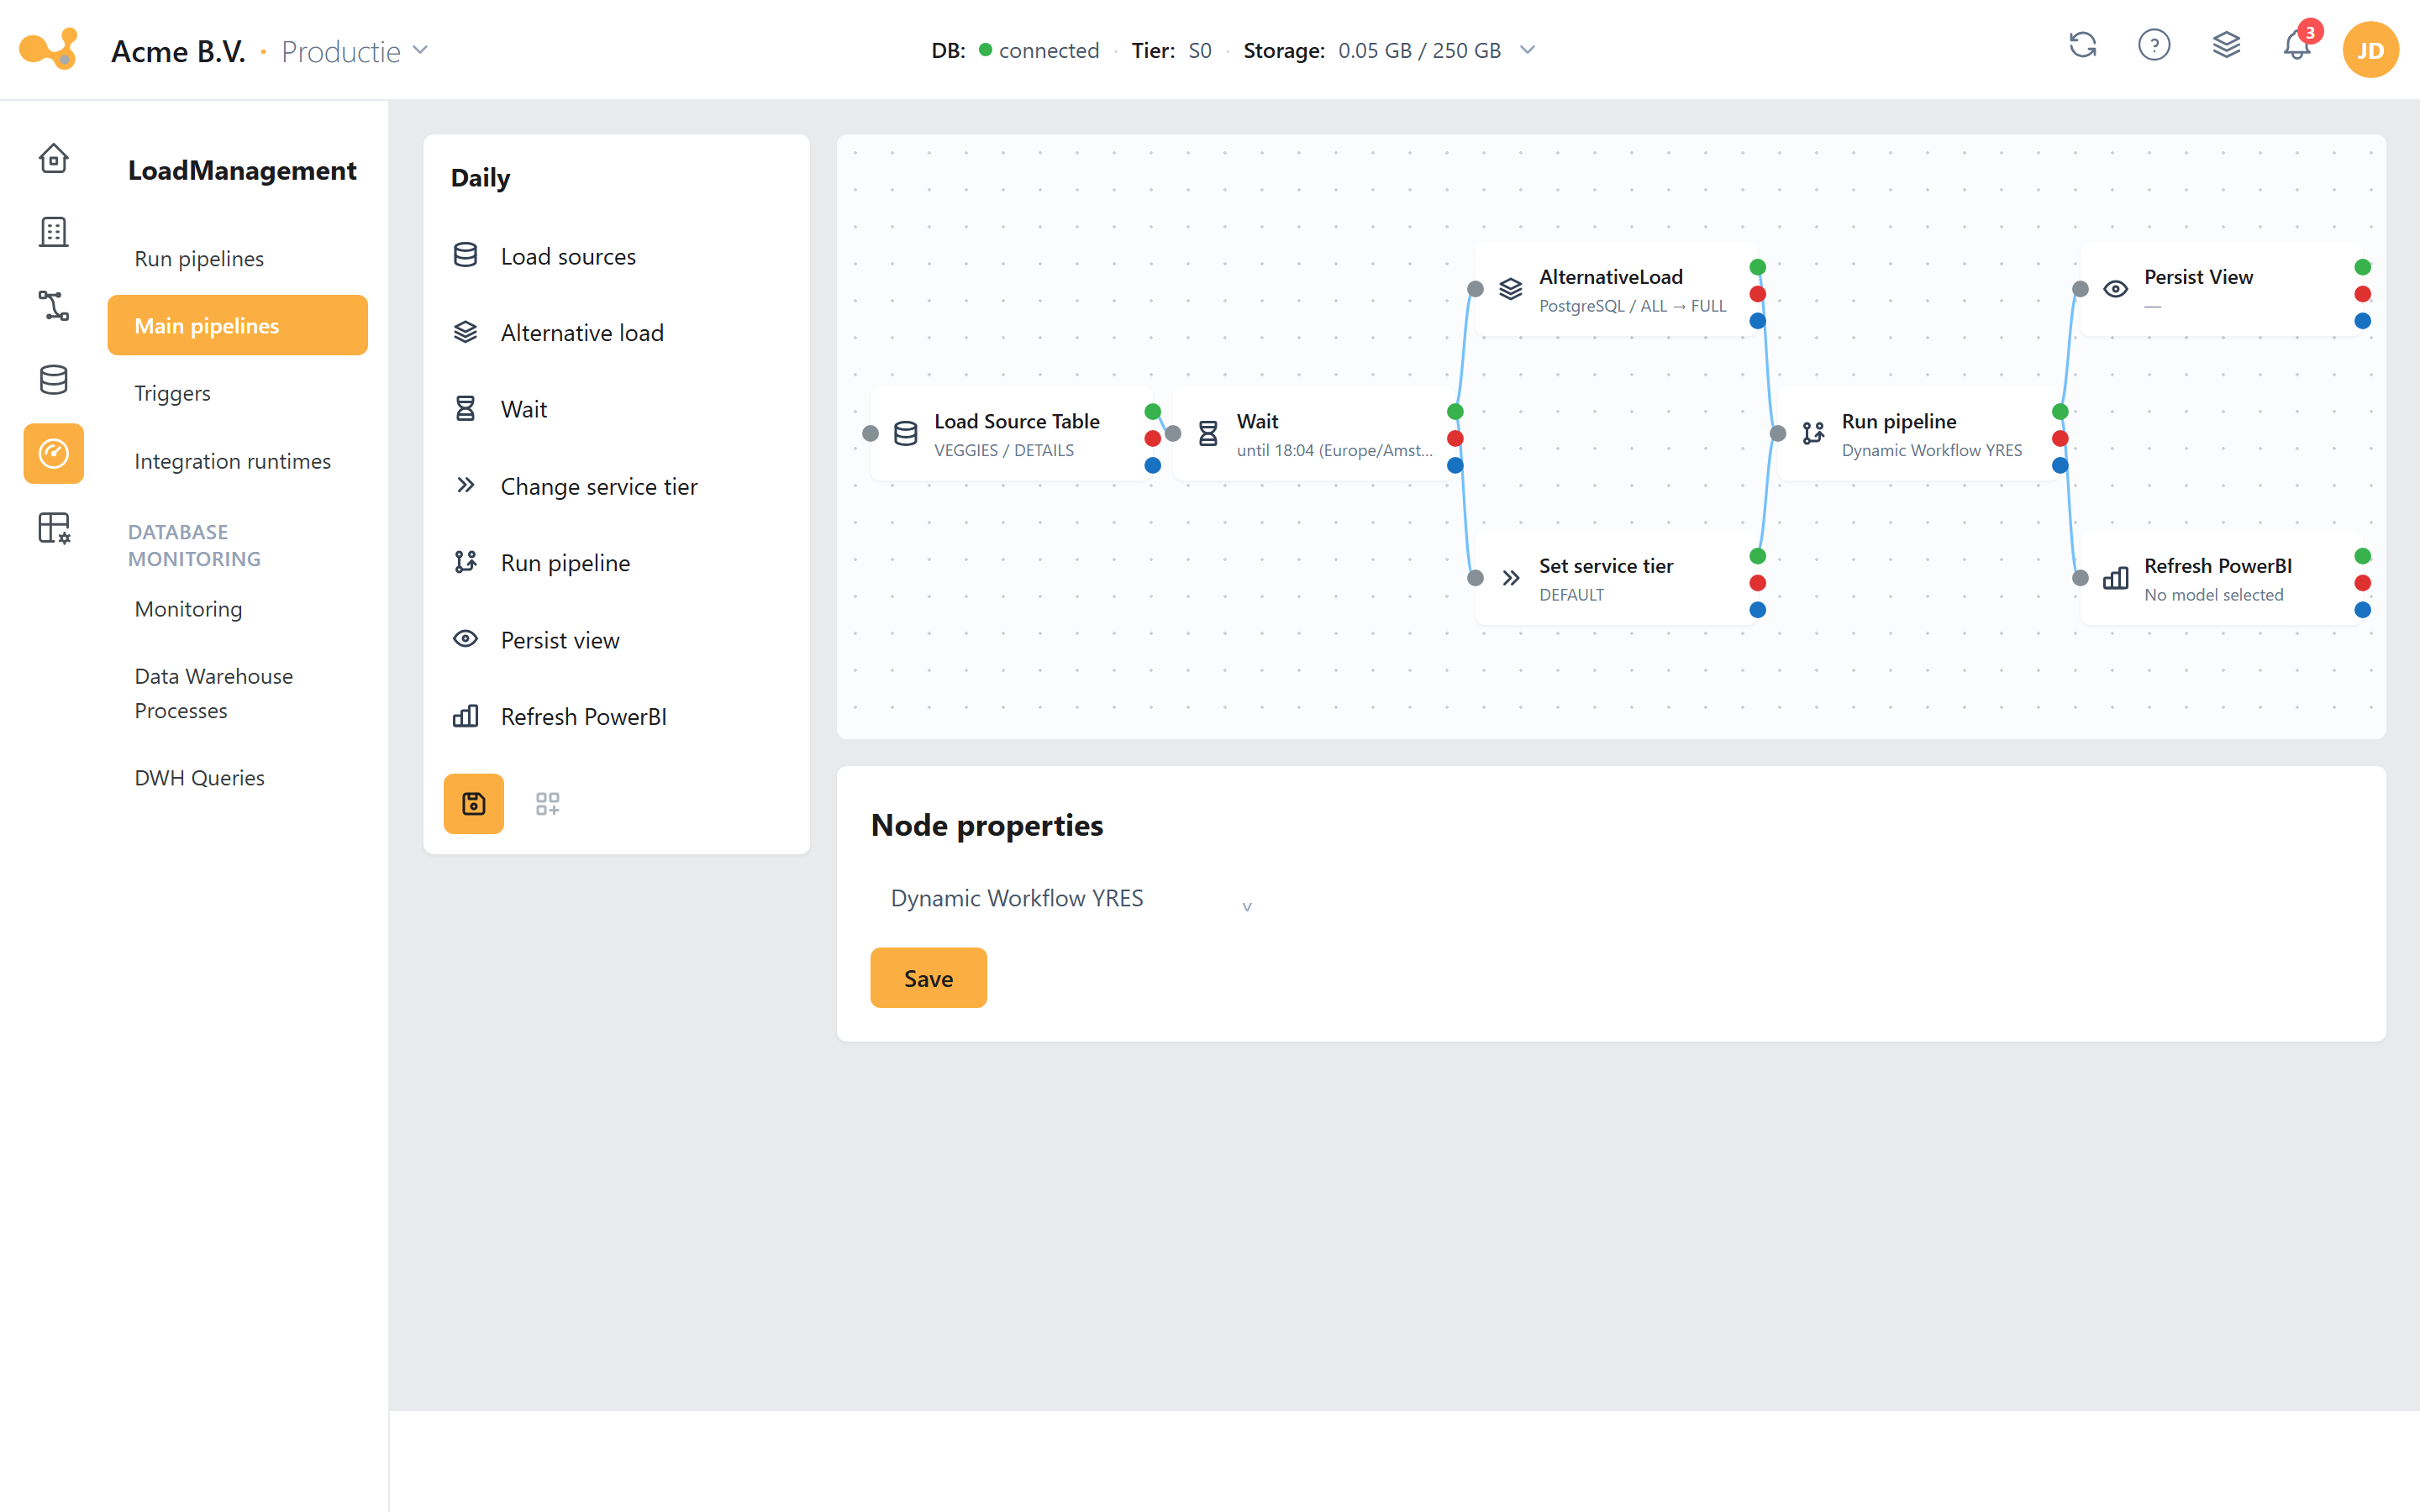
The Design master pipeline screen: drag node types onto the canvas, connect their outputs and publish the flow to ADF.
(1) Node palette on the left — drag a node type onto the canvas. (2) Canvas (reactflow) — connect nodes, select them to configure, delete with Backspace. (3) Three outputs on the right of each node: On success (green), On failure (red) and On completion (blue) — you build the conditional logic with these. (4) Input on the left of a node — connections come in here. (5) Color legend for the three outputs. (6) Save (draft) and Publish (to ADF; only active after a Save).
Steps:
- Open Load Management → Design master pipeline and create a new flow.
- Drag node types from the palette (callout 1) onto the canvas. Available nodes include Load sources, Alternative load, Wait, Change service tier, Run pipeline, Persist view and Refresh PowerBI.
- Connect the nodes by dragging from an output on the right of a node to the input on the left of another node. Deliberately choose On success (green), On failure (red) or On completion (blue) to define your logic.
- Select a node to configure it (for example, with Load sources the source/schema/table).
- Click Save to store the draft.
- Click Publish to generate the flow as an ADF pipeline. The published pipeline appears in the Data Factory (folder
MasterPipelines) and in Run pipelines after a few minutes.
A master pipeline lets you tie existing Yres building blocks (loads, waits, tier switches, view materialization, Power BI refresh) together with success/failure/completion logic. You don't draw individual copy activities or data transformations: you configure nodes and their connections, and Yres generates the underlying ADF pipeline from them. The full list of node types and their points of attention is in Load Management → Master pipelines.
Further reading
- Scheduling maintenance with a master pipeline — apply the master pipeline editor to the periodic maintenance tasks (garbage collection, log retention, archiving, index maintenance).
- Data Engineering — full field-by-field explanation of Materialized views (and View persistence up to and including v1.56) and Database objects.
- Load Management — Run pipelines, Triggers, Monitoring and Master pipelines per screen.
- Data flow — where the Materialize Views step and the Dynamic Workflow fall within the overall load workflow.
- Load types and History & SCD2 — what the chosen load type does with the history of a materialized view.